I am a postdoctoral researcher at the Amsterdam Machine Learning Lab (AMLab) at the University of Amsterdam, working with Jan-Willem van de Meent on scientific machine learning. Previously, I was a postdoc at the Generative AI group at Eindhoven University of Technology, working with Jakub M. Tomczak on neural network quantization. I obtained my PhD from the University of Amsterdam, after starting my doctoral studies at Northeastern University, and hold an MSc in Data Science and a BSc in Artificial Intelligence and Computer Science from the University of Edinburgh.
My research interests broadly lie at the intersection of generative modeling, efficient machine learning, and scientific AI. I am particularly interested in making machine learning more efficient in terms of data, memory, and computation, through representation learning, quantization, and simulation-driven optimization.
Interests
- AI for Fluid Dynamics
- Deep Generative Models
- Quantization
- Representation Learning
- Inference
Education
-
Postdoc, 2025
Eindhoven University of Technology (TU/e)
-
PhD, 2023
University of Amsterdam
-
MSc in Data Science, 2017
University of Edinburgh
-
BSc in Artificial Intelligence and Computer Science, 2016
University of Edinburgh
Featured Publications
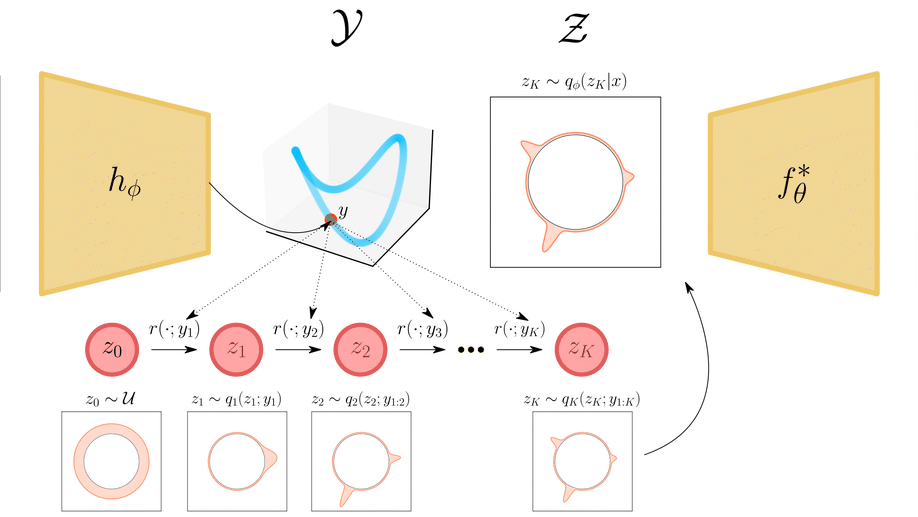
Topological Obstructions and How to Avoid Them
Incorporating geometric inductive biases into models can aid interpretability and generalization, but encoding to a specific geometric structure can be challenging due to the imposed topological constraints. In this paper, we theoretically and empirically characterize obstructions to training encoders with geometric latent spaces. We show that local optima can arise due to singularities (e.g. self-intersection) or due to an incorrect degree or winding number. We then discuss how normalizing flows can potentially circumvent these obstructions by defining multimodal variational distributions. Inspired by this observation, we propose a new flow-based model that maps data points to multimodal distributions over geometric spaces and empirically evaluate our model on 2 domains. We observe improved stability during training and a higher chance of converging to a homeomorphic encoder.
Structured Disentangled Representations
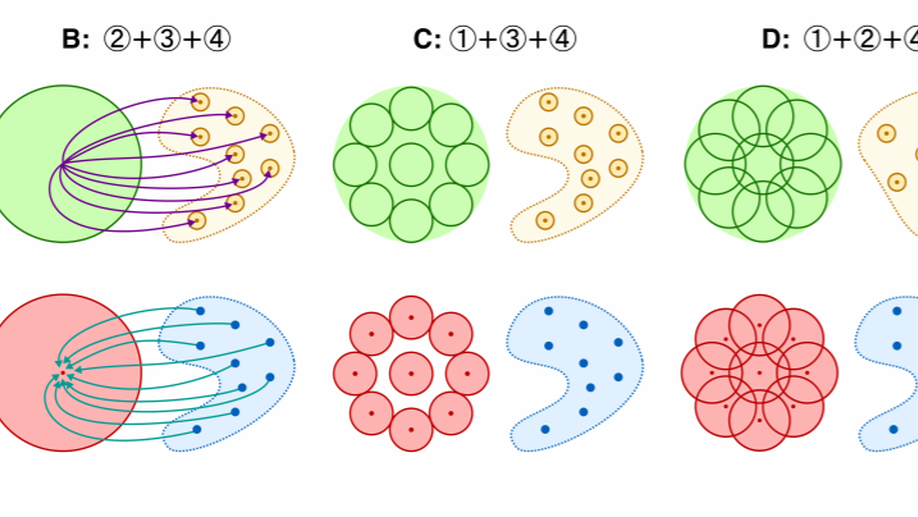
Deep latent-variable models learn representations of high-dimensional data in an unsupervised manner. A number of recent efforts have focused on learning representations that disentangle statistically independent axes of variation by introducing modifications to the standard objective function. These approaches generally assume a simple diagonal Gaussian prior and as a result are not able to reliably disentangle discrete factors of variation. We propose a two-level hierarchical objective to control relative degree of statistical independence between blocks of variables and individual variables within blocks. We derive this objective as a generalization of the evidence lower bound, which allows us to explicitly represent the trade-offs between mutual information between data and representation, KL divergence between representation and prior, and coverage of the support of the empirical data distribution. Experiments on a variety of datasets demonstrate that our objective can not only disentangle discrete variables, but that doing so also improves disentanglement of other variables and, importantly, generalization even to unseen combinations of factors.
Recent Publications
Topological Obstructions and How to Avoid Them
Conjugate Energy-Based Models
Nested Variational Inference
Rate-Regularization and Generalization in VAEs